Logit
Logit 
Education materials shared by the owner.
Logit 
Sliding-window Attention 
Multi-head Attention 
Query, Key, Value 
Attention Steps 
Overfitting 
Denoising Diffusion Probabilistic Mod 
Association SSE 
Markov Decision Process 
Drop Out 
Causal Masked Attention 
Bayes Theorem 

Information Gain 
Naive Bayes 
Autocorrelation Coefficient 
Proximity Categorical Distance 
Pearson Correlation Coefficient 
Sigmoid 
Tanh 
Association Confidence 
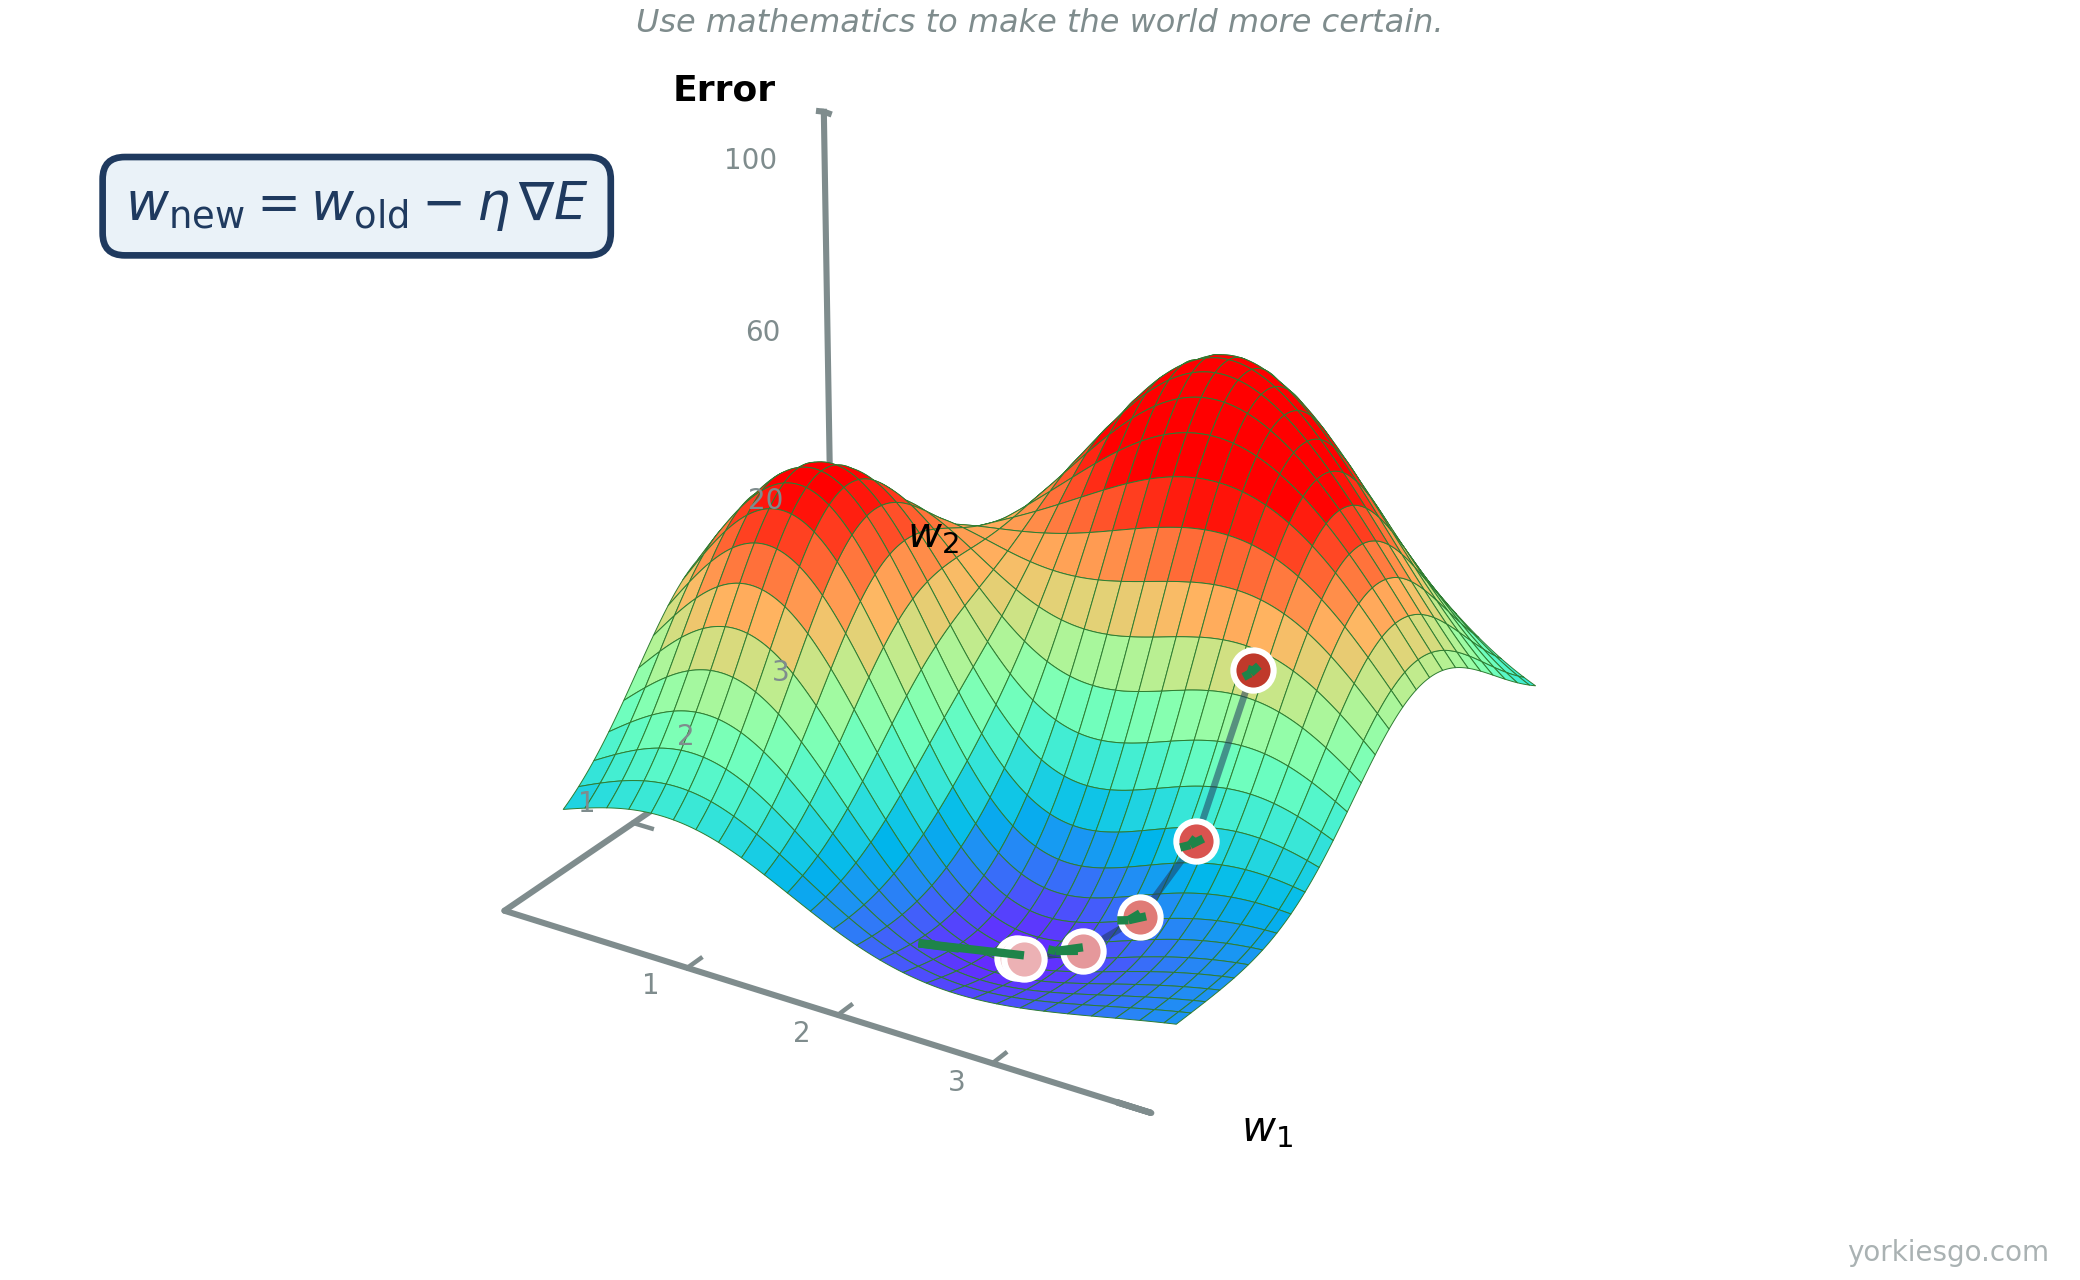
Back Propagation 
K-means 


 # F1 only rewards models that keep precision and recall high at the same time, which makes it the standard single number for positive-class performance.
 # MCC only rewards models that handle both classes well, which makes it the most trusted single metric for imbalanced data.
 # "Every Vote Counts"
# Leave a Feedback or Request a Diagram! 
 # Leave a Feedback or Request a Diagram!
 # Leave a Feedback or Request a Diagram!
 # Leave a Feedback to Request a Diagram.
 # Leave a Feedback to Request a Diagram.
 # Leave a Feedback to Request a Diagram.
 # Leave a Feedback to Request a Diagram.
 # Leave a Feedback to Request a Diagram.
![Two arrows from the origin: blue A(6,2) low and long, orange B(2,6) steep, green arc theta between them labeled cos theta = 0.60. Card reads cos theta = A.B / (|A||B|) = (6x2 + 2x6) / (sqrt(40)…
![Two arrows from the origin: blue A(6,2) low and long, orange B(2,6) steep, green arc theta between them labeled cos theta = 0.60. Card reads cos theta = A.B / (|A||B|) = (6x2 + 2x6) / (sqrt(40)…
![From O1 (1,1) to O2 (4,5): dashed legs go 3 right and 4 up, right-angle marker at the corner, and the blue straight line connecting them is labeled d = 5. Card reads d(O1,O2) = sqrt((x2-x1)^2 +…
![Grid from O1 (1,1) to O2 (4,5): blue horizontal leg of 3 blocks, green vertical leg of 4 blocks, so the walk along the grid is 7 blocks while the straight line measures 5; card reads d = |x2 - x1|…
# The tiny leak that saved ReLU's day  on this site already. This is its playable sibling, plus a third contestant most explainers skip:…
*Every clustering, nearest-neighbor, and recommendation algorithm depends on one choice you make before anything runs: what the word "close" means. There is no universal answer, because the right…
What's new in AI this week: shopping agents went multimodal and in-store, frontier models turned to cybersecurity at scale, image generation got faster, and regulators opened a personalized-pricing…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math to learners of all…
I spent two years at Blueprint Technologies helping build the retail version of a video analytics product -- the system that later became…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math of learners of all…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math to learners of all…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math to graduate students…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math to graduate students…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, deep learning, statistics, and math to graduate students…
# Questions from My Students: "What Is the Difference Between LSTM and GRU?" *This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I…
*This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine learning, statistics, and math to graduate students and working…
# Questions from My Students #5: "Why Does Attention Need More Than One Head?" *This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I…
# Questions from My Students #4: "Why Can't GPT Look Ahead?" *This is a series where I answer the questions my tutoring students really ask -- the ones textbooks tend to skip. I teach machine…
One of my students asked me a question last week that I couldn't answer with a diagram alone: **"How does Delta Network attention actually differ from an LSTM? If the same token arrives with the same…
# Questions from My Students #1: "What Is Attention Actually Doing?" *This is a series where I answer the questions my tutoring students really ask — the ones textbooks tend to skip. I teach machine…
# Emerging AI Weekly — October 30, 2026 *What's new in AI this week: world models, open weights, local AI hardware, enterprise agents, and a $17B grocery deal.* **Emerging Signals:** 1. **Google…